When a client performs a TLS handshake with a server, it sends a piece of information called SNI (Server Name Indication).

Why does it do this? Because a single server can easily host several different TLS certificates on the same IP. If the client doesn’t say “who I’m looking for” during the handshake, the server is left clueless: with so many certificates on hand, which one should it present?

Let’s Walk Through the Timeline

  1. DNS lookup: Translate the domain name into an IP address.
  2. TCP three-way handshake: Knock on port 443 of that IP.
  3. TLS handshake: Negotiate encryption parameters and verify the certificate. SNI is tucked into the ClientHello in this step, the key moment where the client “announces who it is looking for.”
  4. HTTP request: Now data can finally be sent safely through the encrypted channel.

From the ISP’s Point of View

Start with the DNS lookup. It’s usually plaintext, so the ISP can see right through it. Even if you use encrypted DNS, the ISP can still see that you’re talking to some DNS server, though it may not know what exactly you asked. This kind of traffic is generally let through. The TCP handshake is the same: nothing special about it, and it’s usually let through as well.

So here’s the question: if an ISP wants to block certain domains, or only allow domains on a whitelist, where does it start?

The answer is the first step of the TLS handshake, using SNI to determine your destination. The moment the client initiates a TLS handshake, it is, in the ISP’s eyes, loudly announcing: “I’m going to visit such-and-such website!” Whether to let it through is entirely up to the ISP’s policy.

As for ECH (Encrypted ClientHello), let’s set it aside for now.

Interrupting your connection isn’t hard either, and can be done by tampering in the middle: send a TCP RST to each side of the communication, or simply drop packets and leave you waiting.

SNI Spoofing: Putting on a Disguise

Now let’s look at it from the proxy side, and see why SNI spoofing works.

The key is that you have a middleman VPS: traffic goes to the VPS first, and the VPS then forwards it to the real destination. So when establishing the TLS connection with the VPS, you’re free to set the SNI to any other domain. You’re clearly connecting to your own VPS, yet the SNI solemnly declares: “Oh, I’m Google.” As a result, what the ISP sees may be you dutifully visiting Google.

So, observing SNI is indeed an effective means of traffic control. Overall, yes.

But SNI Wasn’t Made for This

I want to stress that SNI was never designed for traffic identification or access control, so being pressed into this job comes with plenty of limitations.

Scenario 1: Better Safe Than Sorry Firewalls

For ISPs or firewalls that would rather wrongly block a thousand than let one slip through, if the SNI you claim is too famous, such as Microsoft or Google, they will likely get suspicious and go a step further, checking whether the destination IP belongs to a known data center or hosting provider, and then decide whether to allow it according to their own policy.

In this case, the relatively safe approach is to use VLESS/VMess + TLS with your own domain and certificate, and play it straight.

Scenario 2: Simple Domain Management Only

Another kind of scenario uses SNI only for simple domain-based access control, such as Wi-Fi on planes and trains: some domains are free to access, while the rest require payment.

In this case, VLESS + Reality combined with a modified SNI may be able to bypass this kind of simple SNI-based access control.


That’s all, just some casual thoughts from a purely technical perspective.
客户端在向服务器进行 TLS 握手时,会发送一个叫作 SNI(Server Name Indication)的信息。

为啥要这么做?因为一台服务器完全可能把好几张不同的 TLS 证书挂在同一个 IP 上。要是握手时不说清楚「我要找谁」,服务器就一脸懵:这么多证书,到底该拿哪张出来见客?

先捋一捋时间线

  1. DNS 查询:把域名翻译成 IP 地址。
  2. TCP 三次握手:敲开该 IP 的 443 端口大门。
  3. TLS 握手:协商加密参数、验证证书。SNI 就藏在这一步的 ClientHello 里,是整个流程里「自报家门」的关键时刻。
  4. HTTP 请求:终于可以通过加密通道安心传数据啦。

站在 ISP 的视角

先说 DNS 查询。它通常是明文的,ISP 一眼就能看穿。就算你用了加密 DNS,ISP 也能看到你在和某个 DNS 服务器聊天,只是不一定知道你具体问了啥。这类流量一般都会被放行。TCP 握手也一样,平平无奇,没什么特别之处,通常也是直接放行。

那么问题来了:如果 ISP 想拦截某些域名,或者只放行白名单里的域名,该从哪下手呢?

答案就是 TLS 握手的第一步,靠 SNI 判断你的目的地。客户端一发起 TLS 握手,在 ISP 眼里就等于大声宣布:「我要去访问某某网站啦!」放不放行,全看它自己的策略。

关于 ECH(Encrypted ClientHello),这里先按下不表。

想打断你的连接也不难,可以在中间动点手脚:给通信双方各发一个 TCP RST,或者干脆直接丢包,让你干等着。

SNI 欺骗:披一件马甲

再从网络代理的角度聊聊,SNI 欺骗为什么行得通。

关键在于你有一台中间商 VPS:流量先到 VPS,再由它转发到真正的目的地。所以在和 VPS 建立 TLS 连接时,你完全可以把 SNI 填成别的域名。明明连的是自己的 VPS,却在 SNI 里一本正经地说:「啊,我是 Google。」这样一来,ISP 看到的可能就是你正在老老实实访问 Google。

所以,观察 SNI 确实是一种行之有效的流量控制手段。总体来说,是的。

但是,SNI 并不是干这个的

我想强调一下,SNI 的设计初衷从来不是用来做流量识别和访问控制的,被拿来干这个活,局限性自然不少。

场景一:宁可错杀一千的防火墙

对于那些宁可错杀一千、不可放过一个的 ISP 或防火墙来说,如果你声称的 SNI 太出名了,比如 Microsoft、Google,它们很可能会多留个心眼,进一步检查目标 IP 是不是已知的数据中心或机房,再按自己的策略决定放不放行。

这时候,相对稳妥的做法是使用 VLESS/VMess + TLS,配上自己的域名和证书,老老实实做人。

场景二:只做简单域名管理的场景

另一类场景,只是用 SNI 做点简单的域名访问权限管理,比如飞机上、火车上的 Wi-Fi:部分域名免费访问,其余的要掏钱。

这种情况下,VLESS + Reality 配合修改 SNI,就有可能绕过这种基于 SNI 的简单访问控制。


以上,纯属技术角度的随想。

I often find myself thinking: at this point in time, when AI can do so many things so well, what capabilities truly remain essential?

The answer, I believe, is the ability to communicate effectively with AI.

The ability to ask the right questions at critical moments.

Or, put another way, to continually refine prompting to approach a potentially optimal LLM output from multiple angles.

There was a time before LLMs arrived. We are people from that era, and we must reflect on what has changed.

Some ask whether we should use AI, and how we should use it. But what about those for whom LLMs have always existed?

When they enter university, Copilot is already a default feature in VS Code.

Or high school students, just stepping into adolescence, already equipped with tools like Doubao that can answer questions better than their teachers.

Or even younger children, who grow up with ChatGPT as a pressure-free social companion, a friend they can confide in.

All of this feels completely natural.

These natives of the AI era never had the option of not using AI, because its existence is already a given in their environment, an established fact, a known variable in their lives.

I still remember the sense of awe the first time I used GitHub Copilot. Watching it automatically fill in what used to be blank, flowing like water, faster even than my thoughts. I tried to chase it with Vim motions, but the Auto completions were always just ahead of where I was about to reach.

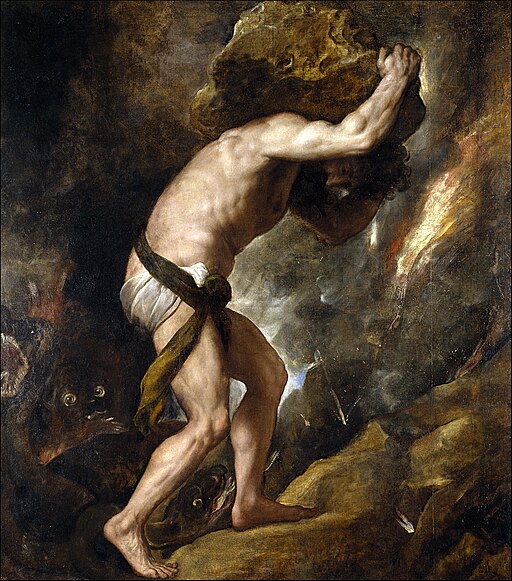
We must believe that Sisyphus is happy.

I know what I am doing.

I also know how this ends.

It’s not a battle that can be won.

Another moment of shock came with my first conversation with GPT-3.5. Science fiction had long imagined many possibilities, but when humanity finally possessed an artificial intelligence that could effortlessly pass the Turing test, the world remained strangely quiet.

As if it were no big deal.

AI has already become part of advanced productivity. Rather than saying it gives you wings, it might be more accurate to say that you, as a human, are becoming the wings of AI. Without you, it cannot take off, but it can still run astonishingly fast. And without it, you are left in the dust, as the rolling wheels of history thunder past, grinding everything beneath them. You are in that dust.

So ask better questions.

Ask about the meaning of the universe. Ask where humanity is headed.

If you can ask a truly good question, you are already very close to the answer.

(中文版就不插图了罢)

我常在思考,时至今日,如果那么多事情 AI 可以做的这么好,那么还剩下什么能力更为关键。

是什么呢?是与 AI 进行有效沟通的能力。

在关键时刻提出合适的问题。

或者说,不断精进 Prompting,从不同维度逼近可能存在的最优 LLM 输出结果。

曾经的确有一个大模型尚未来临的时代。我们是来自那个时代的人,需要思考究竟发生了什么。

有些人会问,我们是否应该使用 AI,以及该如何使用 AI。可是呢,对于那些生活在大模型已然存在的年轻人来说呢?

当他们步入大学时,Copilot 已经成为 VS Code 的标配。

或者那些高中生,他们刚刚进入高中,已经拥有了能够比老师答疑解惑更强的豆包。

甚至是更小的孩子,在成长过程中,ChatGPT 成为了无压力社交,能够倾诉心声的朋友。

非常自然。

这些 AI 时代的原住民没有机会选择不使用 AI,因为 AI 的存在已经是他们成长环境中的既定事实,是一个已知变量。

我还记得自己第一次使用 GitHub Copilot 时那种惊艳的感觉,看到它像流水一样自动填充那些原本的空白,速度之快,甚至超越了我的思绪。我用 Vim Motion 试图不停的追赶,但 AI 的补全总是在我即将触及的前方。

我们必须相信西西弗斯是幸福的。

我知道自己在做什么,

我也知道结局是什么。

打不赢的。

再次震撼的体验,是第一次与 GPT-3.5 聊天的时候。科幻小说当然描绘了许多可能性,但当人类终于拥有了轻而易举通过图灵测试的人工智能时,这个世界却悄无声息。

似乎没有什么大不了的。

AI 已经成为先进生产力的一部分。与其说它让你如虎添翼,不如说,你作为人类,正在成为 AI 的翅膀。没有你,它飞不起来,但它依然跑得飞快。而没有它,你却是在尘埃里,历史洪流滚滚的车轮碾过,那一片尘埃里。

好好地提问吧。

去问一问这个宇宙的意义,去问一问人类将去往何方。

问出了一个真正好的问题,就离答案不远了。

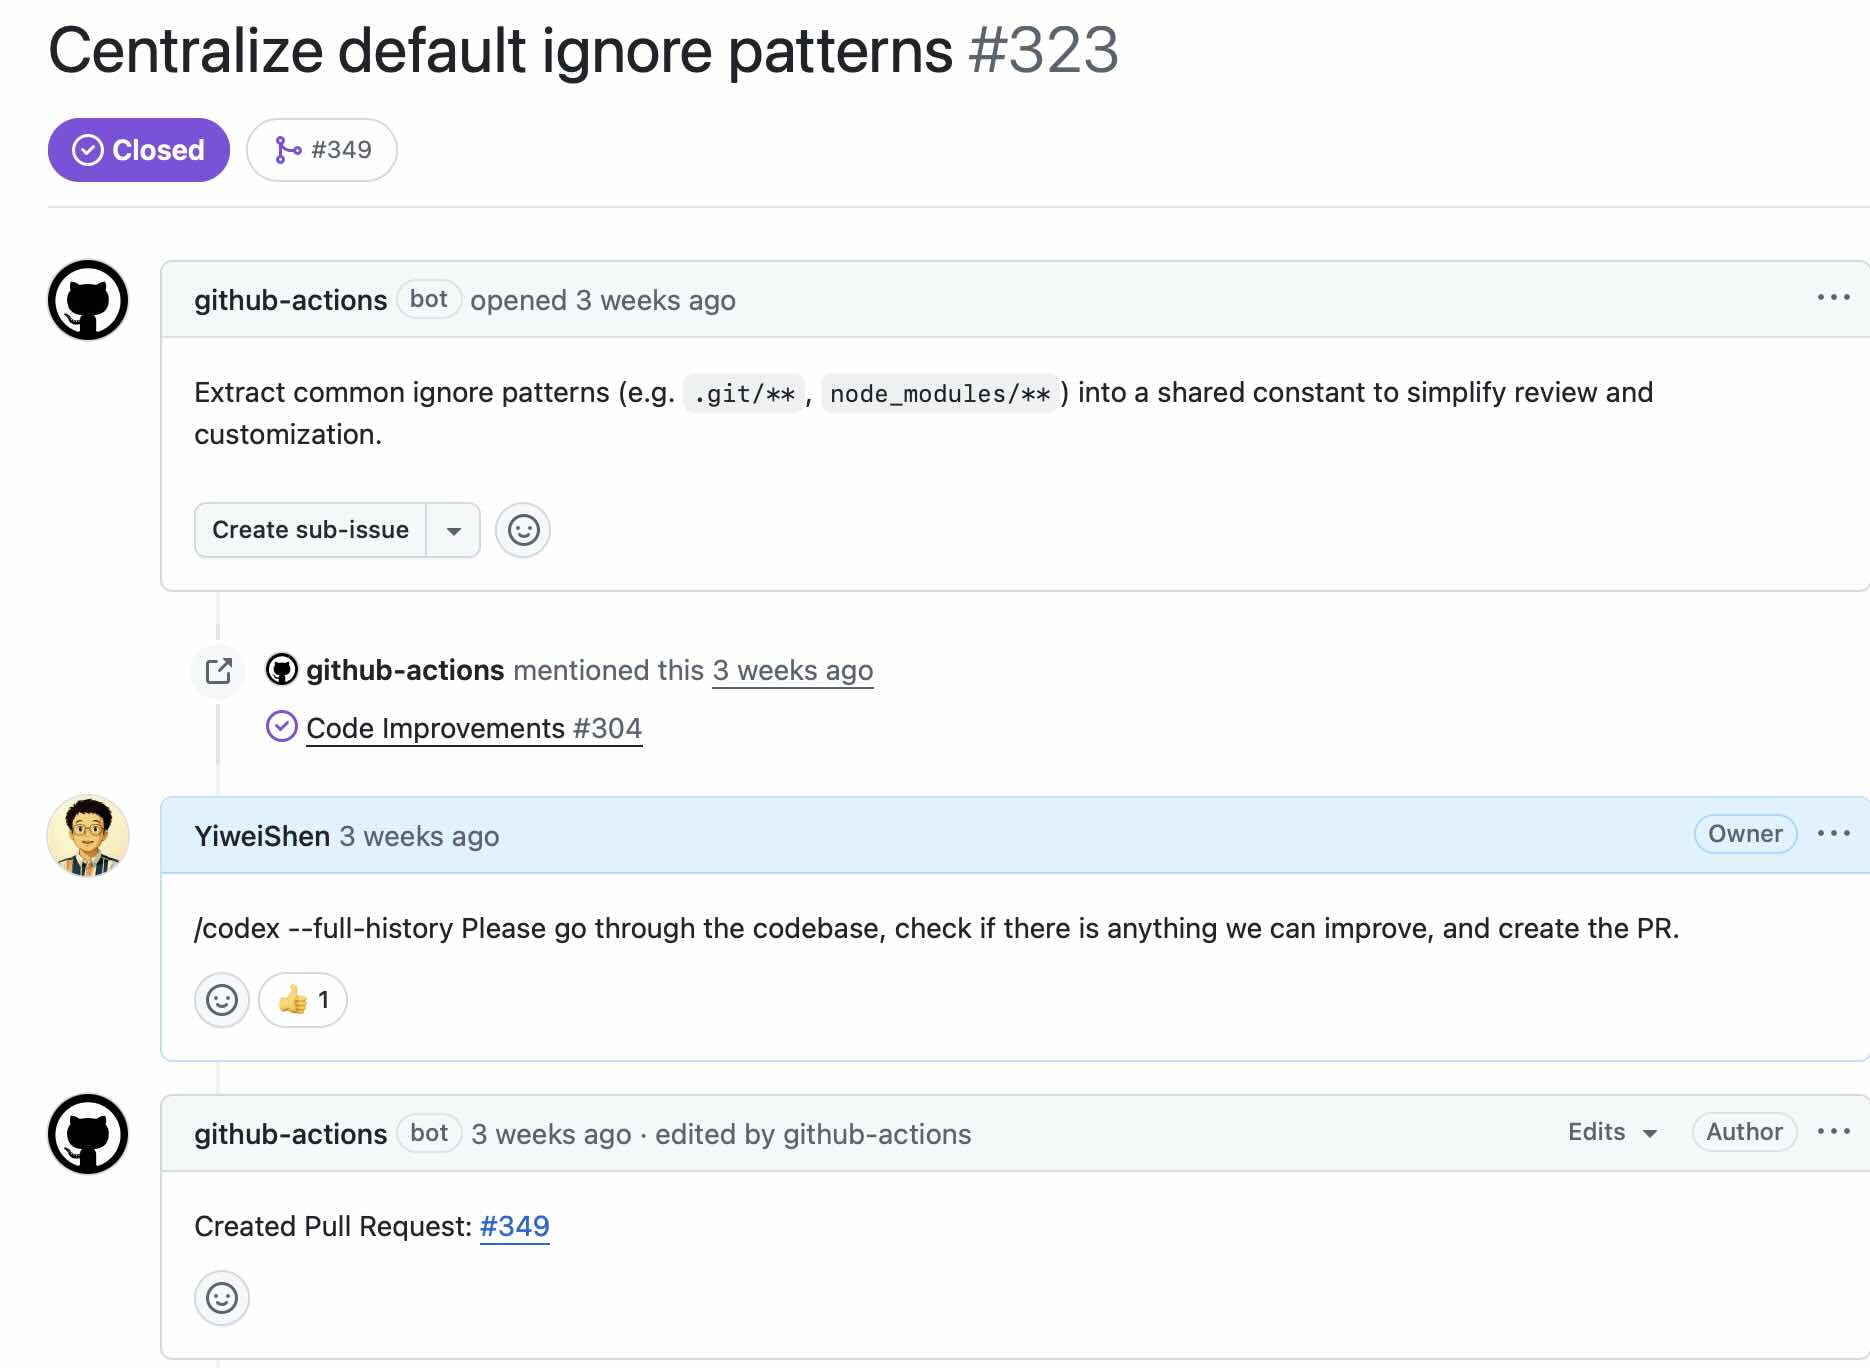
Lately, I’ve been obsessed with Agentic Coding and built a small project called Codez, which runs the Codex CLI directly inside GitHub Actions. It’s been working quite well. Here’s an example of a workflow it supports:

Discuss with AI first → break down the problem → tackle each part one by one

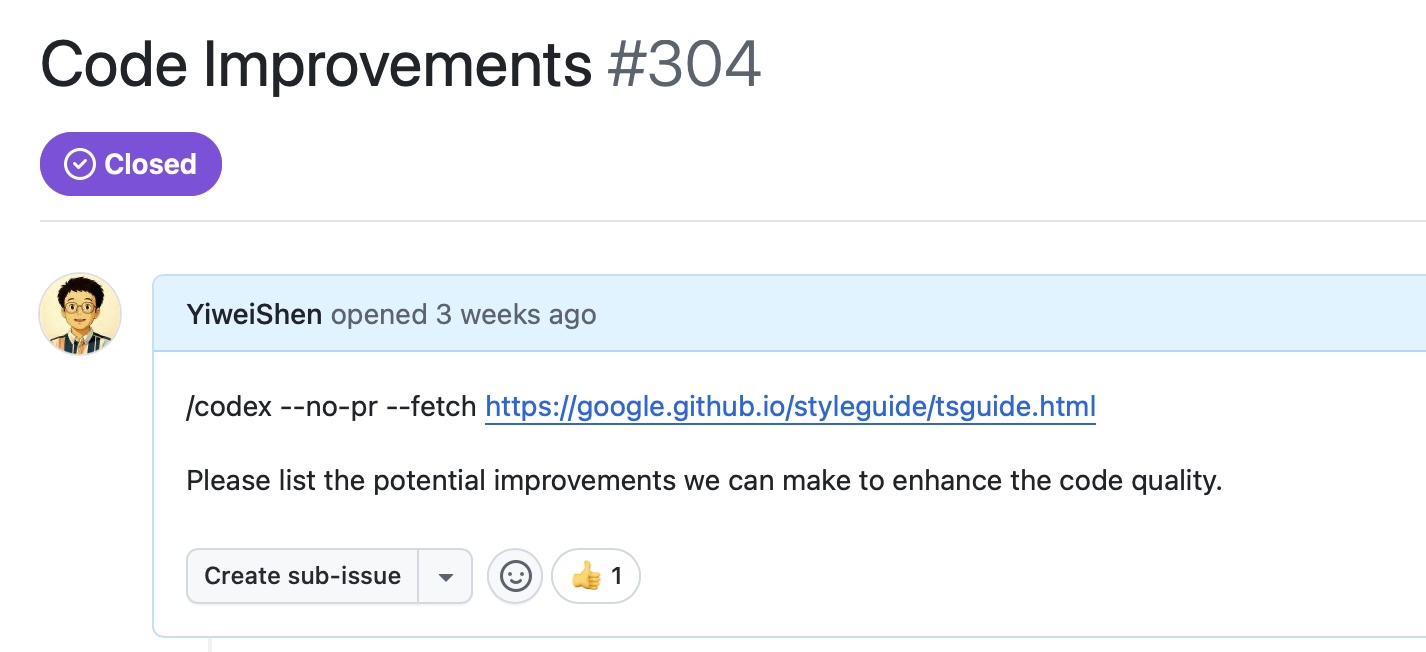
Take this code refactoring request as an example: Issue #304


Step 1: Raise the Requirement

In the issue, I clearly described what I wanted to do, including points to discuss and related background info. The title and content of the issue become part of the initial prompt for the agent.

Then, I triggered the agent directly in the comments:

1
2
3
4
/codex             # Keyword to wake up the agent
--no-pr # Add this flag to prevent it from directly creating a PR. I want to clarify the problem first
--fetch # This flag lets the agent fetch the content from the link for offline use
https://google.github.io/styleguide/tsguide.html # Relevant documentation to help the agent make informed decisions


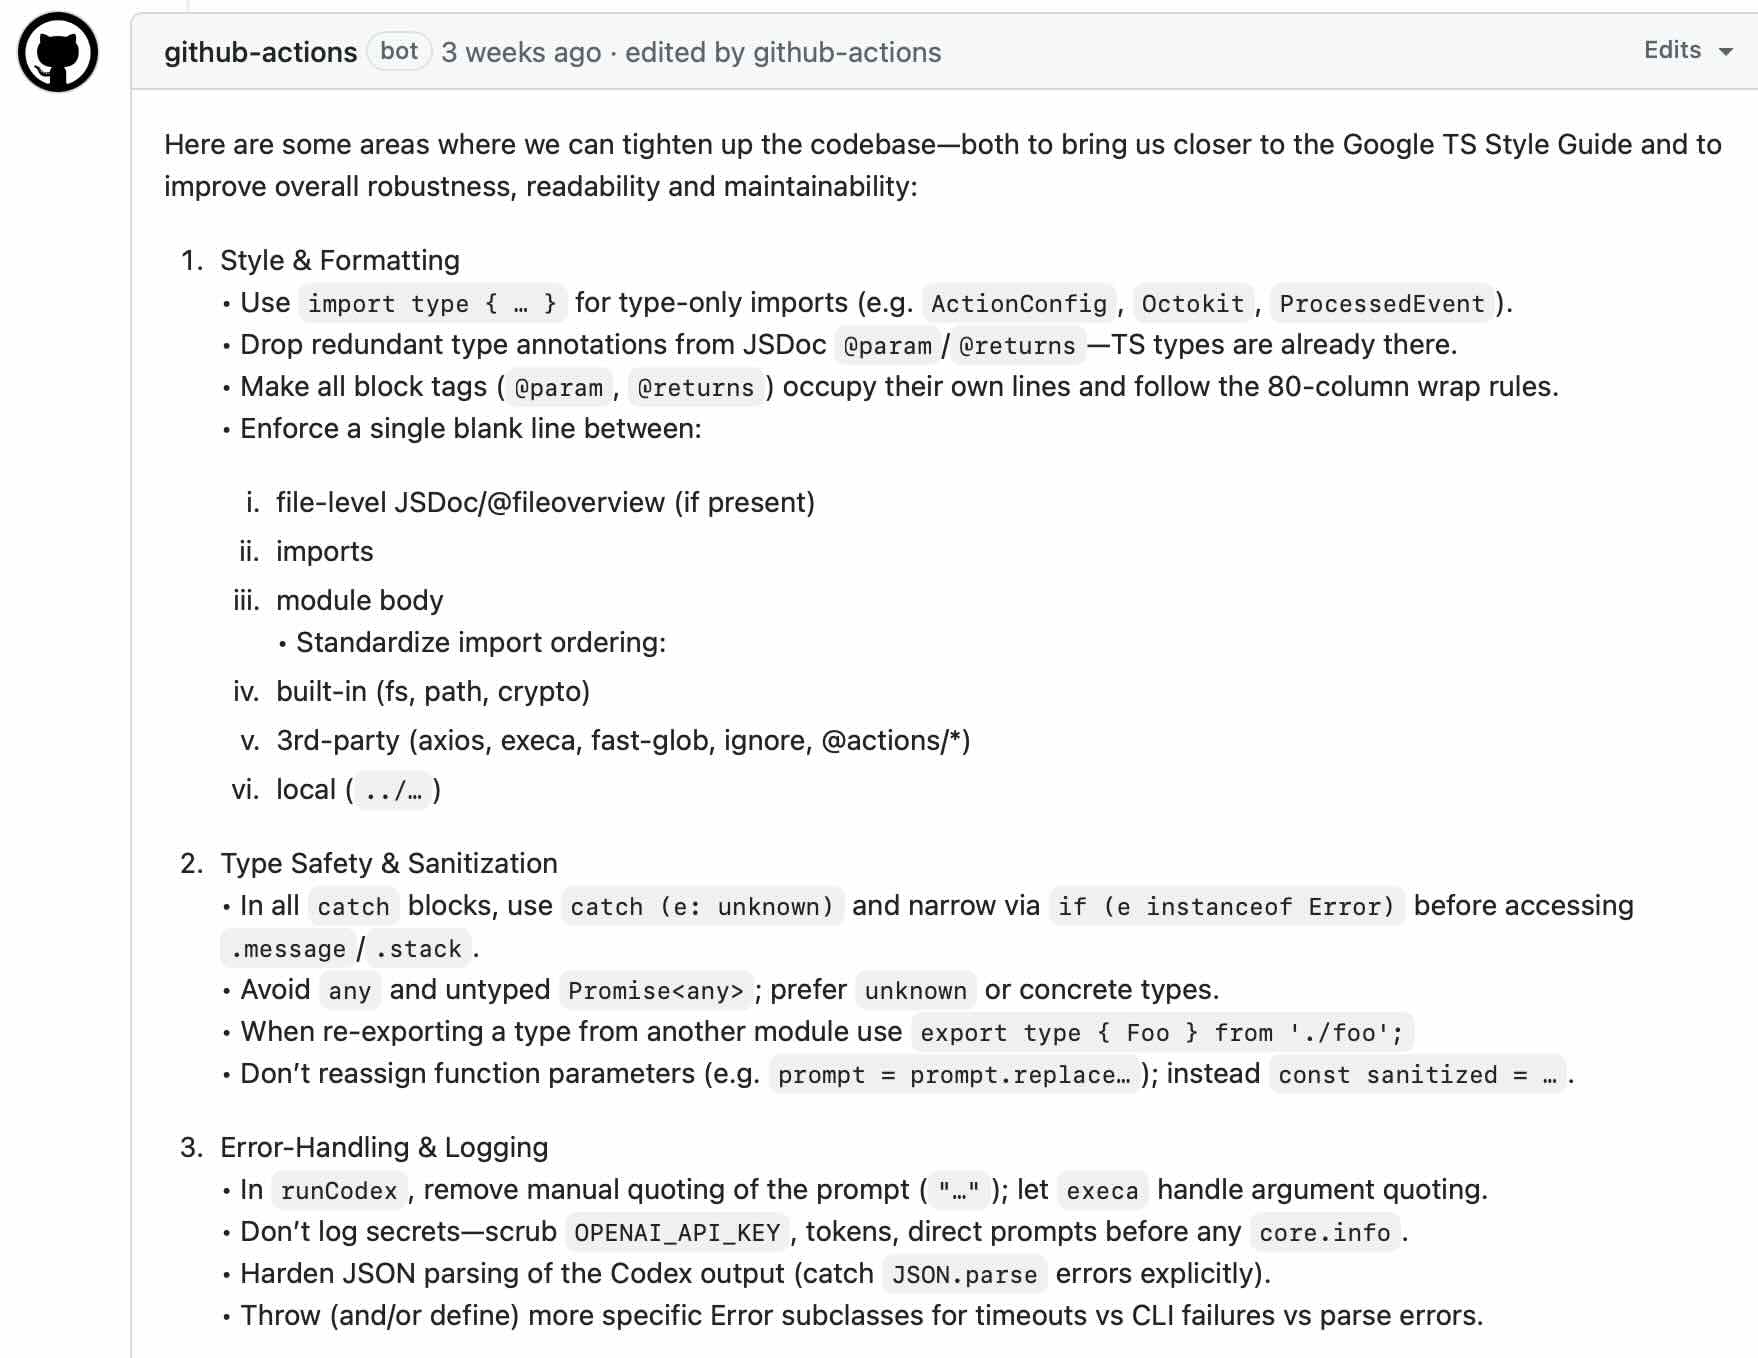
With that, the agent gets to work. Even though it doesn’t have network access during runtime, it can still give some solid initial ideas using the context (codebase, content cached from the provided links, and the issue itself).

Step 2: Automatically Break Down into Actionable Tickets

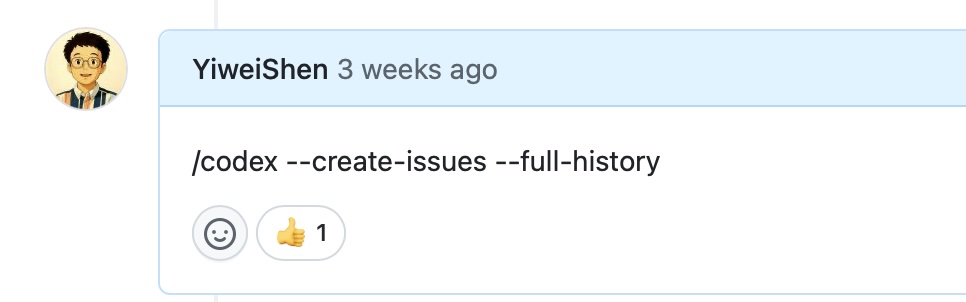
Next, I triggered the agent again. This time to generate a series of issues:


1
2
3
/codex
--create-issues # The model generates a JSON of titles and descriptions, then uses GitHub API to create issues
--full-history # Includes all previous comments in this thread into the context window

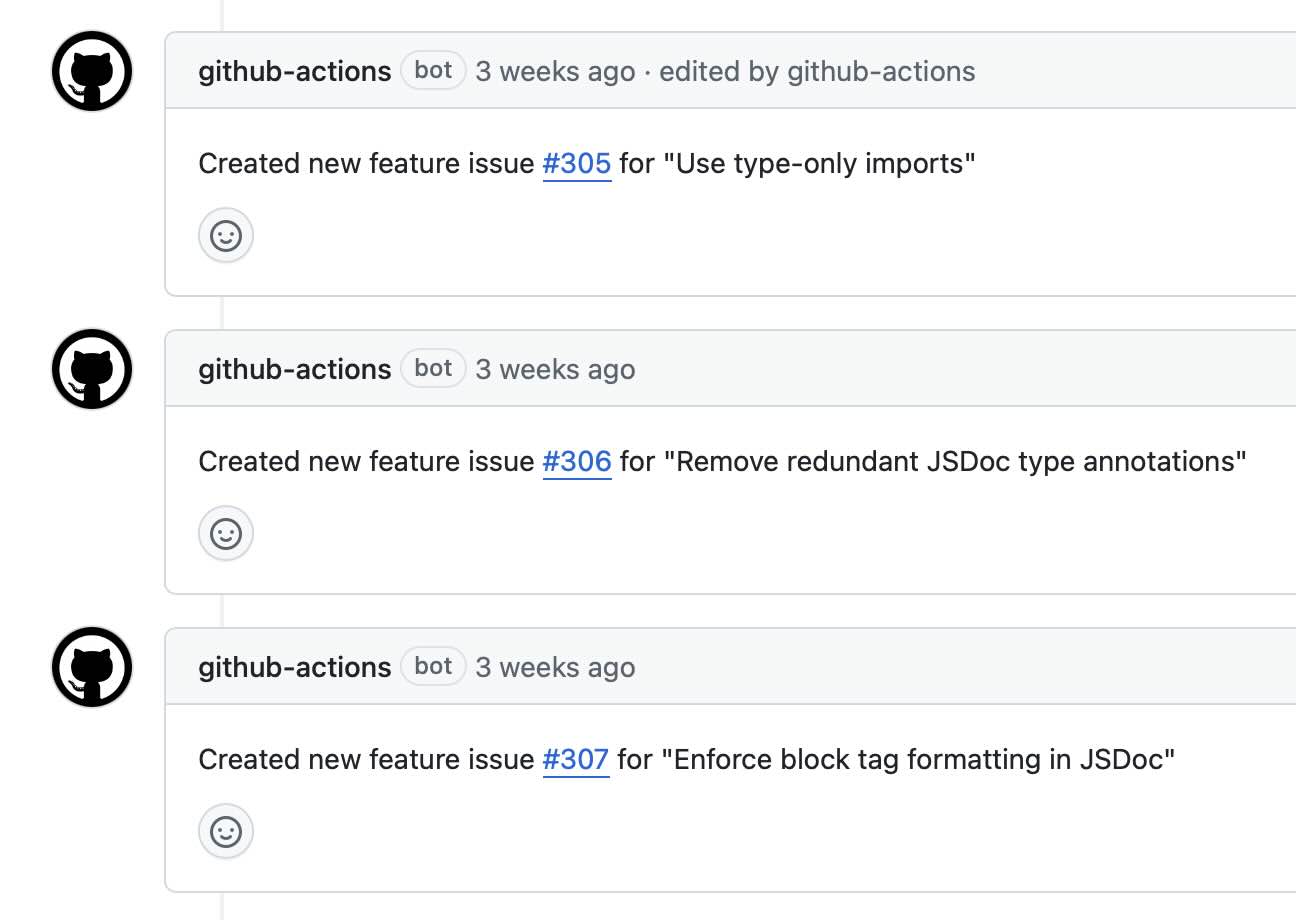
Note: Only flags in the current comment are recognized. The agent then organizes the discussion into multiple issues. Each issue can be worked on independently.


These newly created tickets can now be handled one by one. Like this:

Final Step: Let the Agent Do the Work


The entire workflow feels like genuine team collaboration: discuss first, break down the problem, then work in parallel. The difference is that humans are replaced by agents.

Some say Agentic Coding is like catnip for programmers, totally addictive. It’s true.

最近沉迷于 Agentic Coding,搞了个小项目 Codez,直接嵌在 GitHub Actions 里运行 Codex CLI,效果还不错。可以做这样的工作流:

先和 AI 讨论,然后问题拆解,最后各个击破

比如这个代码重构的需求:Issue #304


第一步:先抛出需求

我在 issue 里写清楚了想做的事,包括要探讨的点、相关的背景资料。这个 issue 的标题和内容,agent 会当成初始 prompt 的一部分。

然后我直接在评论里触发 agent:

1
2
3
4
/codex             # 用关键词唤醒 agent
--no-pr # 加个 flag,不要直接生成 PR,因为我想要把问题先探讨清楚
--fetch # 这 flag 会让 agent 把链接里的内容先抓下来,方便离线使用
https://google.github.io/styleguide/tsguide.html # 提供相关文档,有助于 agent 做判断


这样 agent 就开始工作啦。即便它在运行时没有网络权限,但通过 context(包括 codebase、给的链接、issue 内容),它还是给出了几条挺靠谱的初步思路。

第二步:自动拆解成可执行的 tickets

接着我又触发了一次 agent,这次是让它生成一系列 issues:


1
2
3
/codex
--create-issues # 原理是让模型生成标题加内容的 JSON,然后用 GitHub API 创建 issue
--full-history # 把当前对话前面的所有评论都加入 prompt 进入 context window

注意一下:所谓的 flag 只有当前评论内的 flag 才会生效。现在 agent 把讨论内容整合,分别创建了 issues。每一个 issue 都可以独立地推进。


这些新建好的 ticket 就可以一个一个单独的处理啦。比如下面这样。

最后一步:Agent 干活


整个工作流就像真正的团队协作一样:先讨论,再问题拆解,最后分头干活。不同的是,把人换成了 agent。

有人说,Agentic Coding 就像是程序员的猫薄荷。特别上头。

Let me just say it straight: prompt injection isn’t a bug, it’s a feature.

If you really think there’s some perfect solution to stop all “injections” then in the end, all you’re really doing is trying to police the context window. Kinda like a censorship board, separating out anything they think is harmful.

Why is that?

Because these so-called “injected” prompts are just part of the context like everything else. There’s no real difference between text A and text B. When you put them together into AB, unless you filter the input, there’s not much else you can do. Sure, you can train the model to “self-censor”, that’s doable. But honestly, that makes me feel kind of sad.

As humans, when you read a line like “The bright moon shines between the pines, clear spring flows over the stones” you might picture a quiet forest, a gentle breeze, moonlight. Or when you hear Vivaldi’s Winter, maybe it reminds you of that delicate tension in Portrait of a Lady on Fire. Even under strict rules or social norms, those feelings still burn underneath.

Or maybe we’re just chatting and someone casually drops a phrase like “move mountains like Yu Gong”, or some internet meme, suddenly a flood of meaning and context rushes in.

Is that prompt injection? Technically, yeah.

But that’s also what makes language so powerful. If you try to restrict the context window too tightly, you’re basically cutting off the soul of language.

Now, when I say it’s “unsolvable,” I don’t mean there’s zero technical hope. You can definitely use regex to strip out what you think is harmful, or train a small model to monitor input.

But I want to ask you, why do we need to do that?

We’ve thrown everything, all the words in the world, into training these large models. And still, many people see them as nothing more than small kids. Just like how, to some parents, a kid is never fully grown. Maybe these models will always be “kids” Maybe we all are.

The human brain might be structurally ready at birth, but what really shapes it is training, experience. That’s why fine-tuning matters so much. It’s what decides whether a model can tell when a “dangerous” prompt is actually dangerous. Though honestly, the word “judgment” feels almost too subjective.

We’re so eager to make these models human-like, but we’ve never really stopped to think: what is a human?

We want these models to understand ethics, to follow the rules, and yet we forget that we humans are still struggling in the gray areas ourselves.

先说我的结论:提示词注入,不是 bug,是 feature。

如果你真以为能有一种万能的办法控制所谓“注入”的问题,那你最终能做的,也不过是对上下文窗口进行审查。就像广电总局那样,把被认为有害的内容隔离出来。

为什么呢?

因为“注入”的提示词本来就是上下文的一部分,文字 A 和文字 B 之间并没有本质区别。当它们组合成 AB 时,除了做输入过滤,你别无选择。当然,你也可以通过训练让模型学会“自我审查”,这当然是可以的。但说实话,这让我感到一种深深的悲哀。

作为人类,当你读到“明月松间照,清泉石上流”,脑海中浮现的是空谷幽林、清风明月;当你听维瓦尔第的《四季·冬》,会想起《燃烧女子的画像》中那种暧昧而克制的情愫。即使在礼教之下,那种情感依然燃烧不息。

或者当我们交谈时,随口提到一个四字成语,“愚公移山”,又或者随便提一个网络梗,大量信息就这样瞬间来到了我们的语境之中。

这些是提示词注入吗?是的。

而这正是语言的魅力。你要是禁锢语言的上下文窗口,就是在阉割思维。

我说这是“无解”,并不是说技术上完全无计可施。你当然可以用正则表达式清除那些所谓有害的信息,或者训练一个小模型监控输入内容。

但是,为什么我们还要这么做呢?我们倾尽所能,拿人世间所有的文字,去训练出的大模型,在很多人眼中依旧是个“不成熟的孩子”。就好像父母眼里永远长不大的孩子。也许大模型也永远会是一个孩子,就像全人类一样。

人类的大脑,虽然在出生时结构已经具备,但真正让它生出沟壑的,是后天的训练。所以微调才那么重要。它决定了模型在接收到某些“危险提示”时,是否具备判断力。虽然“判断”这个词听起来太主观了。

我们太急于让模型像人,却从未认真反省过,人究竟是什么。

我们希望大模型懂伦理,守规矩,却忘了人类自己尚且在灰暗中挣扎。

A “paradigm” is not just a form—it’s a mode of thinking.

As a branch of the writing profession, programmers interact with tens of thousands of lines of code, and naturally, they rely on paradigms for guidance. It’s like having a built-in “system prompt”—you don’t need to explain “what object-oriented programming is” to your colleagues every time, nor do you have to argue endlessly about the details of design patterns. There’s an unspoken understanding that you’re “playing by the rules” in a certain context.

After all, the human “mental window” is limited in size. Collaborating without a paradigm is like chickens talking to ducks—utter miscommunication. If you insist on piling all your functions into a single file with no abstraction or categorization, the consequence is writing documentation until you break down.

But now that artificial intelligence is part of the programmer’s workflow, paradigms are shifting.

First, the way we handle code has transformed from “manual carving” to “semantic understanding.” Those obedient little “coding assistants” can automatically modify your code based on a single instruction. So under this transformation, do traditional coding paradigms still matter?

It depends on your perspective.

They do matter—because large language models deal in language. The clearer the linguistic structure, the easier it is to extract and recreate information. It’s the difference between a pile of unclassified documents and a meticulously organized file cabinet. The information entropy is not the same, and naturally, neither is the efficiency.

But from another angle, maybe they’re no longer that important. After all, paradigms were originally for humans to read. Now, LLMs can develop their own paradigms—or even revive those long-abandoned “classical practices.” For instance, directly manipulating binary code: who needs layers of abstraction? From a model’s perspective, that quaint notion of “human readability” might be completely unnecessary.

Second, there’s the transformation of the programmer’s role. Whether we accept it or not, this wave of change has quietly pushed us into a new position. The days of hand-crafting code were like seasoned artisans refining woodwork—there was a kind of pride and dignity woven into every character.

But from a business standpoint, when websites and apps are the final product, the programmer is just one link in the industrial chain. Whether you code by hand or use AI to generate it, the user doesn’t care. Our mindset must shift accordingly. I am not just a code porter or a keystroke operator—I am an engineer solving problems. Writing code is a means to that end, not the end itself.

To me, the value of paradigms lies in helping us organize our thoughts, so that our future selves—or others—can quickly get into the zone when reading our code. This was once a form of self-rescue for programmers. But now, LLMs effortlessly surpass us. They have stronger memory, faster analysis, and even if your code is a mess, they can still make sense of it.

So, do we still need paradigms in the future?

Perhaps the real question is: are we willing to hand over our thinking to the model, or do we want to preserve a trace of human logic?

Paradigms are road signs in the world of programming.

But when the roads are no longer built by humans—does that mean we are no longer travelers, or just moving where the machine tells us to go?

所谓“范式”,是一种形式,更是一种思维模式。

程序员,作为文字工作者的一个分支,要与成千上万行代码打交道,自然离不开各种范式的指引。就像预设好了一个“系统提示”,你无需一遍遍向同事解释“什么是面向对象”,也无需在设计模式上争论太多细节。大家心照不宣,默认你在某个语境下是“按套路出牌”。

毕竟,人类的“思维窗口”大小有限,没有范式的合作无异于鸡同鸭讲。你要是硬把所有函数堆在一个文件里,不做任何抽象、分类,那后果就是写文档要写到崩溃。

可当人工智能加入程序员的工作流之后,范式正在发生变化。

首先,代码的处理方式从“手工雕刻”变成了“语义理解”。那些听话的“编程小助手”,听你一句指令,便能自动修改代码。那么,这种转变下,传统代码里的范式还重要吗?

这得看你怎么看。

重要,当然重要。因为大模型处理的是“语言”,语言的组织结构越清晰,越有利于信息的提取和再创造。这就像未经分类的文件堆和精心整理过的档案柜之间的差别,信息熵不一样,效率自然也不一样。

但换个角度,也可以说它已经不那么重要了。毕竟,以往的范式,是为了“人”阅读。而现在,大模型完全可以发展出自己的范式,甚至回收那些早被人类嫌弃的“古典做法”。比如说,直接操作二进制编码,何须讲究抽象层级?对于模型来说,那点“人类的可读性”,恐怕只是多余。

其次,是程序员身份的转变。不论内心是否接受,这股变化的洪流,已经悄然将人推到了新的位置。手搓代码的岁月,有点像老手艺人打磨木工制品,那种纯手工的尊严和骄傲,仿佛藏在每一个字符之间。

但若从商业角度看,当网页和 App 成为最终商品时,程序员不过是产业链条上的一环。你是用手搓,还是让 AI 帮你画,用户并不关心。思维也要随之转变。我不只是代码的搬运工、软件的敲字员,而是一个解决问题的工程师。写代码,是解决问题的手段,绝不是唯一答案。

在我看来,范式的意义,是帮助我们整理思绪,好让将来的“自己”或“他人”在回头阅读这些代码时,能更快地进入状态。这本来是程序员的一项自救之术,如今,却被大模型轻松超越。它记忆力更强,分析力更快,哪怕你写得一团糟,它也能看出门道。

那么,未来还需要范式吗?

也许真正的问题是:我们愿意把思维交给它,还是愿意保留一点属于人类自己的逻辑痕迹?

范式,是程序世界中的路标。

而当道路不再由我们铺设,是否意味着,我们也将不再是旅人,而是被路指引的方向?

0%